bag.coffee: A Live Index of Specialty Coffee in Stock
 First Press Studio
I am building bag.coffee, a live index of specialty coffee in stock right now. Today it tracks 190 bags from 41 US roasters, refreshed about once an hour. Each bag has origin, variety, process, altitude, tasting notes, and price normalized to 100 grams. A $61 Gesha and an $18 Colombia can sit on the same page. It is in private beta with a few dozen people on it. I am still building it.
The pipeline
Most roasters sell on Shopify. I start the scraper with one catalog fetch per roaster. It compares product handles against hashes in the database. Unchanged products get a timestamp. New or changed ones queue a targeted scrape. Anything missing or locked is marked unavailable. Only changed pages go to the extraction model. It turns each product page into a structured record: origin, farm, producer, variety, process, fermentation, altitude, roast, notes. A bean score filters out subscriptions and merchandise. Roasters off Shopify get a full browser scrape. A staleness check marks anything not seen in three intervals. I kept the scheduler dumb on purpose. It only decides who is due.
Evals
Extraction can go wrong quietly. I built the eval loop before the homepage. promptfoo runs 14 golden cases through Gemini Flash, Claude Haiku and Claude Sonnet side by side. It scores 14 fields with weights: origin country counts double, process and varieties one and a half, description a tenth. I use exact match for countries, set F1 for tasting notes, and altitude within 100 meters. Every run uploads to Langfuse as traces with a score per field. A regression shows up as a number on a field, not a feeling. The same traces showed that two products re-extracted every hour accounted for 24 percent of one month's extraction spend. The bug cost about five dollars. It was worth finding.
Design
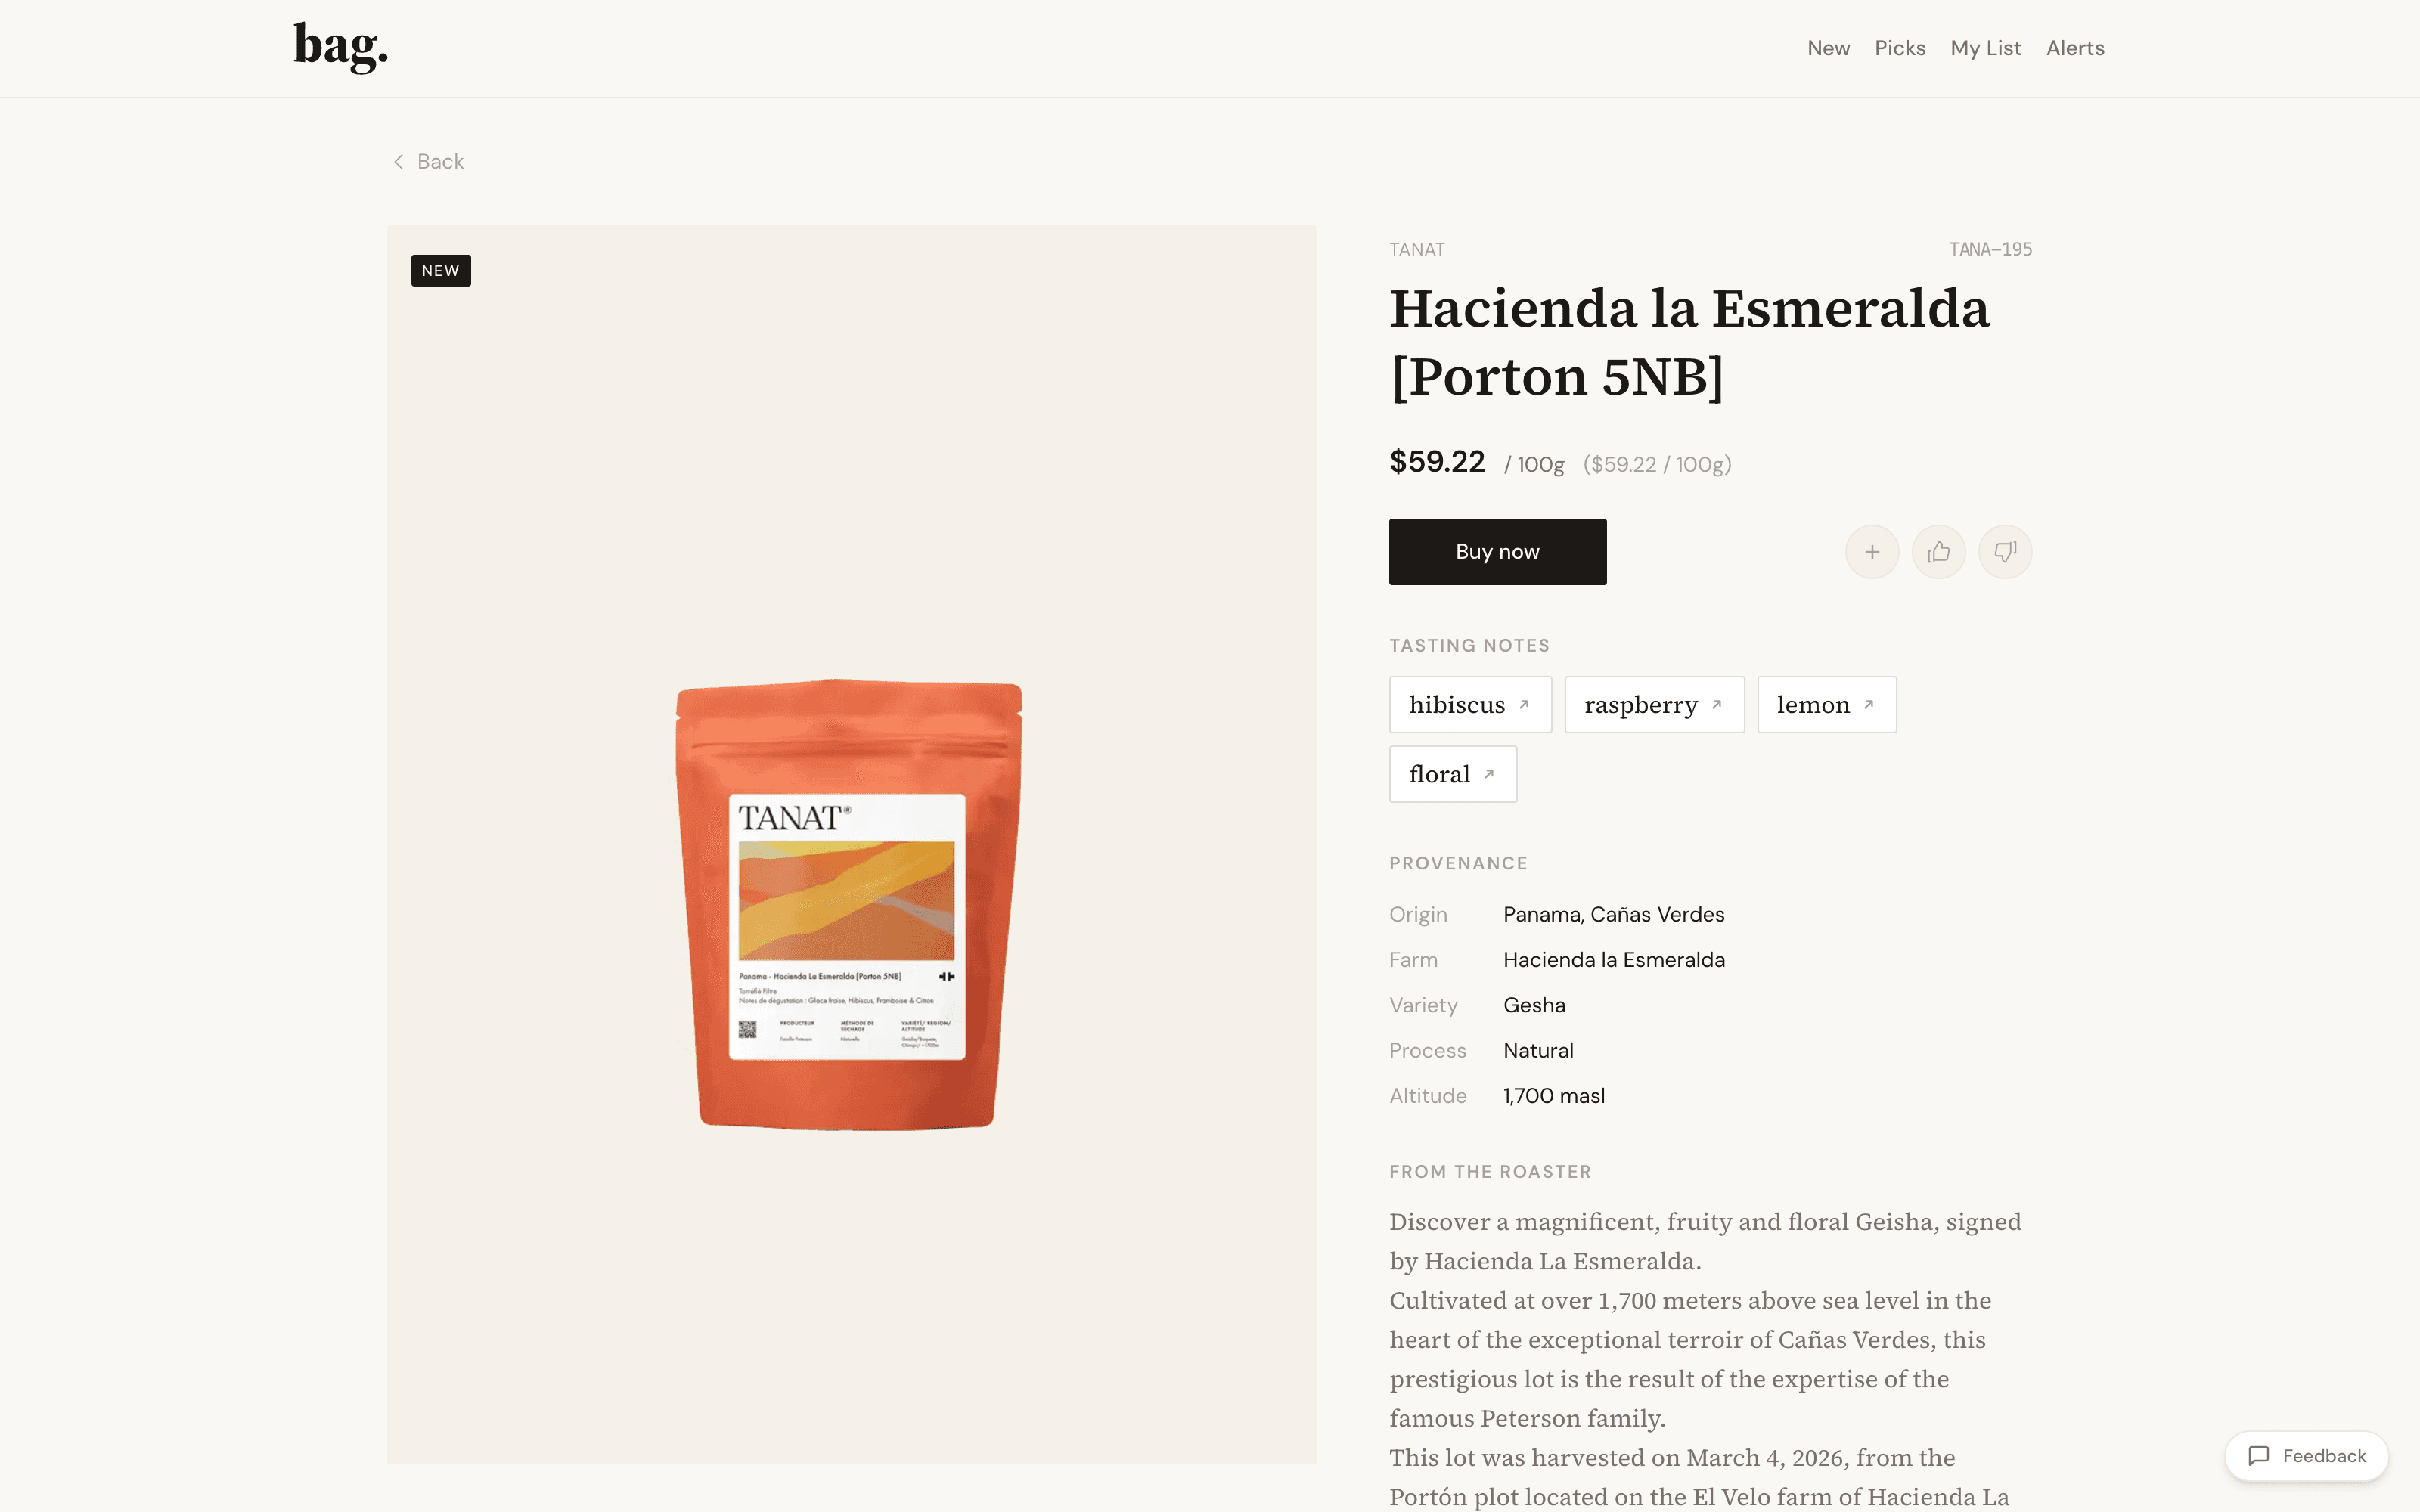
The interface is warm and editorial on purpose. Paper, not white. Ink, not black. Source Serif for the coffee and DM Sans for the controls. A coffee page reads like a magazine spread: the bag on the left, the notes, provenance, and the roaster's own words on the right. Empty states say what is missing and what to try next. Saved searches send an alert when a matching bag lands. A Picks section carries dated editorial drops.
Stack
I use Next.js on Cloudflare Workers. A Workers API sits in front of PlanetScale Postgres with Drizzle. Postgres full-text search is weighted by field. Images are hashed into R2. PostHog handles analytics. Claude Code wrote a good share against specs I wrote.